Table of Contents
Start your free trial.
Start your free trial.
Start your free trial.

Table of Contents
Executive Summary
You are accountable for what ships. Not just whether the pipeline passed, but whether what passed is actually safe to release. Those are two different things, and if you have been managing an engineering team for any length of time, you know the gap between them well. The fix is not better CI; it is a test orchestration layer that turns release decisions into evidence.
CI is green. Deployment happens. Production incident follows. The post-mortem circles back to a test that should have caught it, in an environment that was not configured quite right, with results that nobody was watching closely enough to notice.
That gap is not a people problem. It is a test orchestration problem.
The release confidence gap
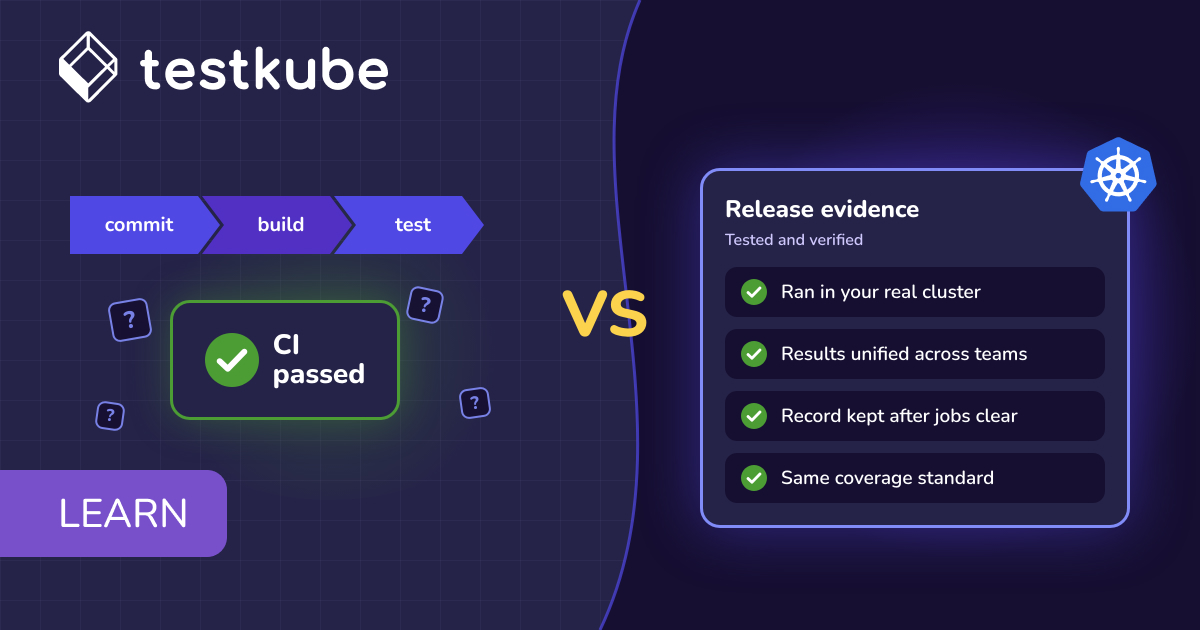
The signal most engineering managers rely on is CI status. Green means ready. But CI pipelines were designed to move code through stages, not to give you a reliable read on whether a release is safe.
Tests run in CI runners that sit outside your actual infrastructure. They do not see the same networking, the same service configuration, the same data characteristics your production environment has. Results that come back green in that context can still fail in the environment that matters. This is exactly the environment mismatch problem most teams have lived through.
On top of that, test results in most engineering organizations are scattered. QA has their tools. Platform has their monitoring. Different teams run different suites with no shared visibility into what ran, what passed, and what was skipped. When something goes wrong, the investigation starts from scratch because nobody has a unified record of the pre-release test state.
Engineering managers in this situation describe the same frustration: they cannot prove to leadership that the team is ready to release, because the evidence does not exist in a form anyone can point to. CI passed is not the same as tested and verified.
Why CI/CD pipelines cannot solve this
CI/CD pipelines are delivery systems. Their job is to get code from commit to deployed as efficiently as possible. They are not test orchestration systems, and when you ask them to act like one, you get a series of problems that compound over time.
Pipeline execution times balloon
When test suites grow, they slow down every pipeline run. Developers waiting 45 minutes for CI feedback stop trusting the process and start looking for shortcuts.
Test coverage fragments
Each team manages their own pipeline configuration. There is no shared catalog, no standard for what gets tested where, no way to see across teams whether coverage is adequate or full of holes. This is the pipeline sprawl problem in action, and it gets worse as the engineering org grows.
Environment mismatches go undetected
Tests pass in CI and fail in production. The pipeline reports success because the tests ran and exited cleanly, not because they validated anything meaningful about how the application behaves in its real environment.
The result is that release confidence becomes a judgment call rather than something you can demonstrate. You ship when it feels right, not when you have evidence.
AI-generated code makes the gap wider
Coding agents now write a large share of the code many teams ship. Some teams produce 10x the code they did two years ago. Review capacity has not grown to match.
That puts more weight on the test signal than it was built to carry. A deployment lead at a large consumer company put it this way: an LLM writes 5,000 lines of code, then writes 10,000 lines of tests for it, and now someone has 15,000 lines to review. If the same model wrote the code and the tests, a passing run proves very little by itself.
When code volume outpaces review, engineering managers need three things from testing:
- Tests that run in the real environment. Agent-written code that passes against mocks or an outside runner can still break in the cluster.
- A record of what ran and what passed. Reviewers can move from line-by-line reading to checking that the right tests ran and passed, but only if that record exists.
- Human-written and AI-written tests in one place. Teams can see which suites cover a change and compare results, no matter who or what wrote them.
For a deeper look at validating tests that agents write, read When agents write the tests. For enforcing standards on AI-generated code at build and deploy time, see governance as code.
What a test orchestration layer gives engineering leaders
A dedicated testing platform with test orchestration built in provides what CI/CD pipelines structurally cannot. Five things change when this layer exists.
A single view of what ran and what it means
When all test results flow into one place, across every tool, every team, and every environment, you stop chasing logs across five different systems to understand pre-release state. One dashboard, one record, one place to point when someone asks whether the release is ready. This is what real centralized test observability actually delivers.
Tests that run in your actual infrastructure
A testing platform built for orchestration runs tests as native jobs inside your real clusters, not in CI runners sitting outside them. Tests validate behavior in the environment they will ship into, which makes the results meaningful rather than approximate.
Execution decoupled from pipeline schedules
Tests can be triggered by commits, by schedules, by events, or on demand, independently of what the delivery pipeline is doing. You can run a full regression suite before a critical release without blocking the pipeline. You can schedule nightly runs against production-like environments without engineer involvement.
Consistent execution across teams
A shared test catalog means every team runs against the same standard. No more N teams with N different configurations producing N different definitions of "passing." Coverage gaps become visible because they are measured against a common baseline.
Faster investigation when things do break
When a failure happens, the data to investigate it is already collected, structured, and kept. Logs and artifacts stay after jobs clear. AI failure analysis summarizes what went wrong across logs, so engineers start from a diagnosis instead of a raw log dump. Failure categories sort failed tests by type and route alerts to the right team. Teams on weekly release trains use this to diagnose pipeline failures before the release deadline. MTTR drops because the starting point for investigation is information rather than a hunt for information.
Visibility into flaky tests
Flaky tests teach teams to ignore red. Once people rerun until green, the pipeline stops working as a signal. With every execution kept in one place, intermittent failures show up across runs, so teams can fix or isolate those tests instead of guessing.
How Testkube provides this layer
Testkube is a testing platform that brings test orchestration toecontainerizednvironments. Engineering managers who have tried to build this capability inside CI/CD pipelines know what that looks like: months of engineering time, fragile custom tooling, and a system that works until it does not and nobody knows how to fix it.
Testkube provides the dedicated layer instead.
It runs inside your clusters. Tests execute where your applications run. Results reflect real environment behavior. The gap between "CI passed" and "safe to ship" narrows because testing happens in conditions that match production.
It gives every team a shared catalog. Test workflows are defined as Kubernetes CRDs and versioned with application code. Any team can trigger them. Any pipeline can call them. Results aggregate centrally regardless of which team ran what.
It decouples testing from delivery. Your CI/CD pipeline triggers Testkube. It does not own test logic. Pipelines stay fast. Test coverage stays comprehensive. Neither has to compromise for the other.
It reports results where release decisions happen. Your pipeline calls Testkube and gets pass or fail back, so it can block a deploy on real-environment results. The GitHub app runs workflows on pull requests and posts the results as checks, with no GitHub Actions setup required.
It reduces onboarding and maintenance overhead. New engineers inherit a shared test catalog, not a bespoke pipeline setup they need weeks to understand. Existing tests do not need to be rewritten. The complexity that accumulates inside pipeline YAML moves to a system designed to handle it.
It works with the tools your teams already use. k6, Playwright, Cypress, Postman, JMeter, custom scripts. Testkube orchestrates them without requiring migration. Teams keep their testing tools. You get the coordination layer above them.
What changes when release confidence is built on evidence
Engineering managers who have implemented test orchestration describe a shift in how releases feel. Not because the risk disappears, but because the evidence exists to assess it properly.
Production incidents that trace back to environment mismatch become rarer, because tests run in real environments. Investigation time after failures drops, because the data is already there. The conversation with leadership about release readiness changes from "the pipeline is green" to a record of what was tested, where, and what the results were.
That is not a workflow improvement. It is a different relationship between quality and delivery.
Building the layer your pipelines cannot provide
If CI status is the primary signal your team uses for release confidence, and production incidents keep happening anyway, the pipeline is not the problem and optimizing it will not fix it.
What is missing is a test orchestration layer: a dedicated system for managing test execution across your containerized environment, collecting results from every team and every tool, and giving you the visibility to make a release decision based on evidence rather than instinct.
Testkube is the only testing platform built to do that.
Frequently asked questions
{{banner-get-started}}
About Testkube
Testkube is the open testing platform for AI-driven engineering teams. It runs tests directly in your Kubernetes clusters, works with any CI/CD system, and supports every testing tool your team uses. By removing CI/CD bottlenecks, Testkube helps teams ship faster with confidence.
Get Started with a trial to see Testkube in action.