Table of Contents
Start your free trial.
Start your free trial.
Start your free trial.

Table of Contents
Executive Summary
A testing AI agent's execution location is where its actions run: the tool calls that touch your source code, test data, credentials, and clusters. That location matters more than where the model or chat lives, because a testing agent can't do its job with less access.
AI agents have moved from demos into pilots and production workflows across parts of the software development lifecycle (SDLC). Many testing tools now ship AI-powered assistants that triage failures, flag flaky tests, or open PRs with fixes attached. Most announcements focus on speed and skip where the agent's actions actually execute.
For a testing AI agent, the systems it can reach include source code, test data, service credentials, and cluster topology. That makes execution location a lot more consequential than it is for a scheduling bot or a support assistant.
This post covers why execution location is becoming a core architectural question for testing AI agents, whether the agent lives in an IDE, a CI/CD workflow, a testing platform, or an in-app assistant.
What governance gaps do AI agents create?
AI agents now generate code and unit tests, set up infrastructure, and orchestrate tests across every phase of software delivery. Governance hasn't kept up, and teams adopting agents run into four gaps.
- Approval is the exception, not the rule. 80.9% of technical teams have already moved into active testing or production with AI agents, but only 14.4% had every agent go live with full security or IT approval first (Gravitee, February 2026, 900+ respondents).
- Monitoring hasn't kept pace with deployment. Only 47.1% of an organization's AI agents are actively monitored or secured, on average, meaning more than half of all agents running today aren't being actively watched at all.
- Agents aren't being treated as their own identity. Machine identities, including AI agents, now outnumber human identities 109 to 1, and AI agents are expected to grow 85% this year (Palo Alto Networks, 2026 Identity Security Landscape). Yet only 21.9% of teams treat an agent as its own identity-bearing entity instead of an extension of whoever configured it.
- Agent definitions drift between teams. One team's testing agent runs on a different set of analysis instructions than another's, for the same task, because there's no enforced source of truth for what "the agent" is supposed to do. A shared execution platform closes this gap by keeping every run tied to the same agent definition.
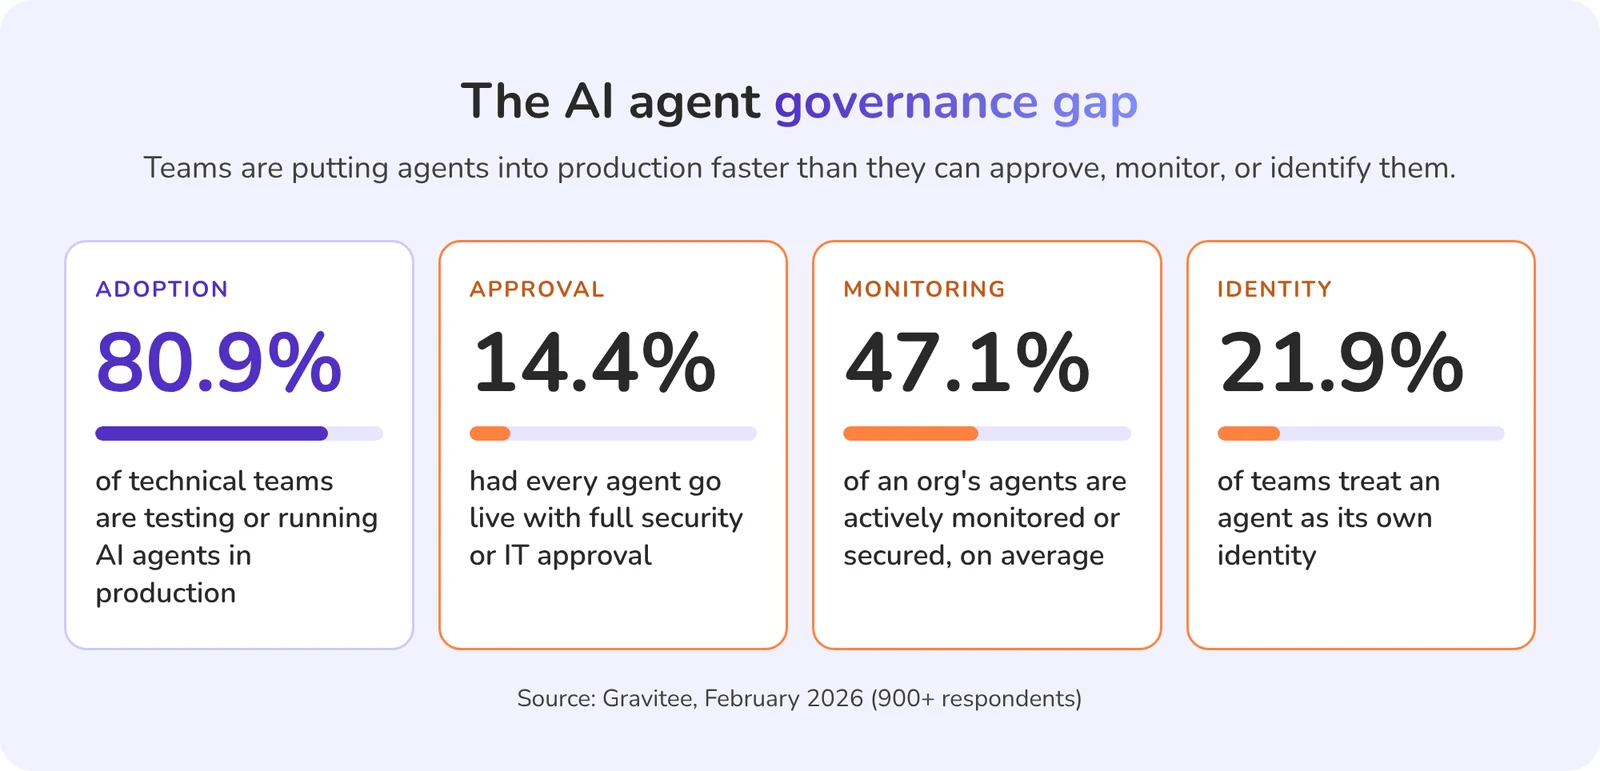
The common thread is the split between model behavior and execution access. Model safeguards govern what an agent is likely to do. Execution access governs what it can reach, no matter which model is behind it. Autonomous agents are a new class of privileged non-human identity.
Why are testing AI agents riskier than other agents?
Testing agents are riskier because the access they need can't be scoped down without breaking the job. A scheduling agent can be scoped down to a calendar API. A support agent can live entirely inside a ticket queue. Neither loses much of its usefulness when its access is narrowed.
Testing agents don't get that same option, because the access they need is the job itself, not an add-on to it.
Whether the agent is embedded in a testing product, triggered from CI/CD, or invoked by an external AI assistant, here's what a testing agent actually needs just to function:
The important thing to understand is that a scheduling or support agent can be scoped down without losing its value. A testing agent can't if any of these are taken away.
Which means the only lever actually available to a team adopting one of these is not whether the agent has this access, but where that access gets exercised. That's the question the rest of this post is built around.
Where does an AI agent reason vs. where does it act?
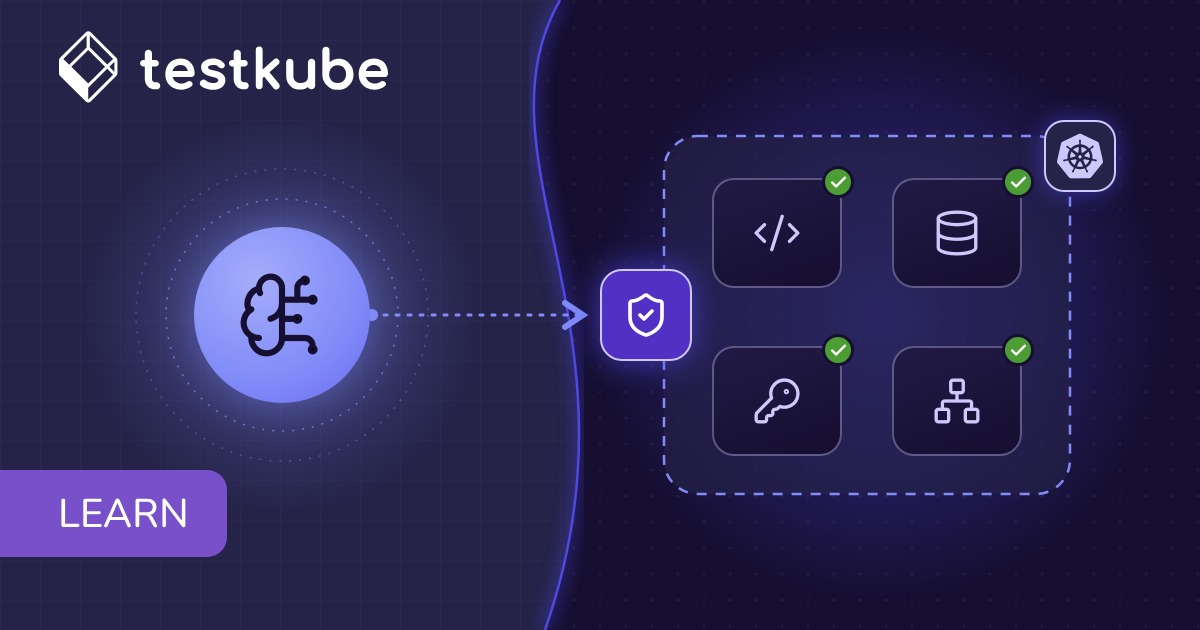
An AI agent reasons where its model call runs and acts where its tool calls touch your systems. Most vendor conversations don't clearly separate where an agent reasons from where an agent acts. The reasoning part is the model call, the prompt, and the orchestration logic that decide what should happen next. The acting part is the tool call that actually touches code, data, credentials, test infrastructure, or production-like environments. For testing AI agents, that distinction matters more than the product surface the user interacts with.
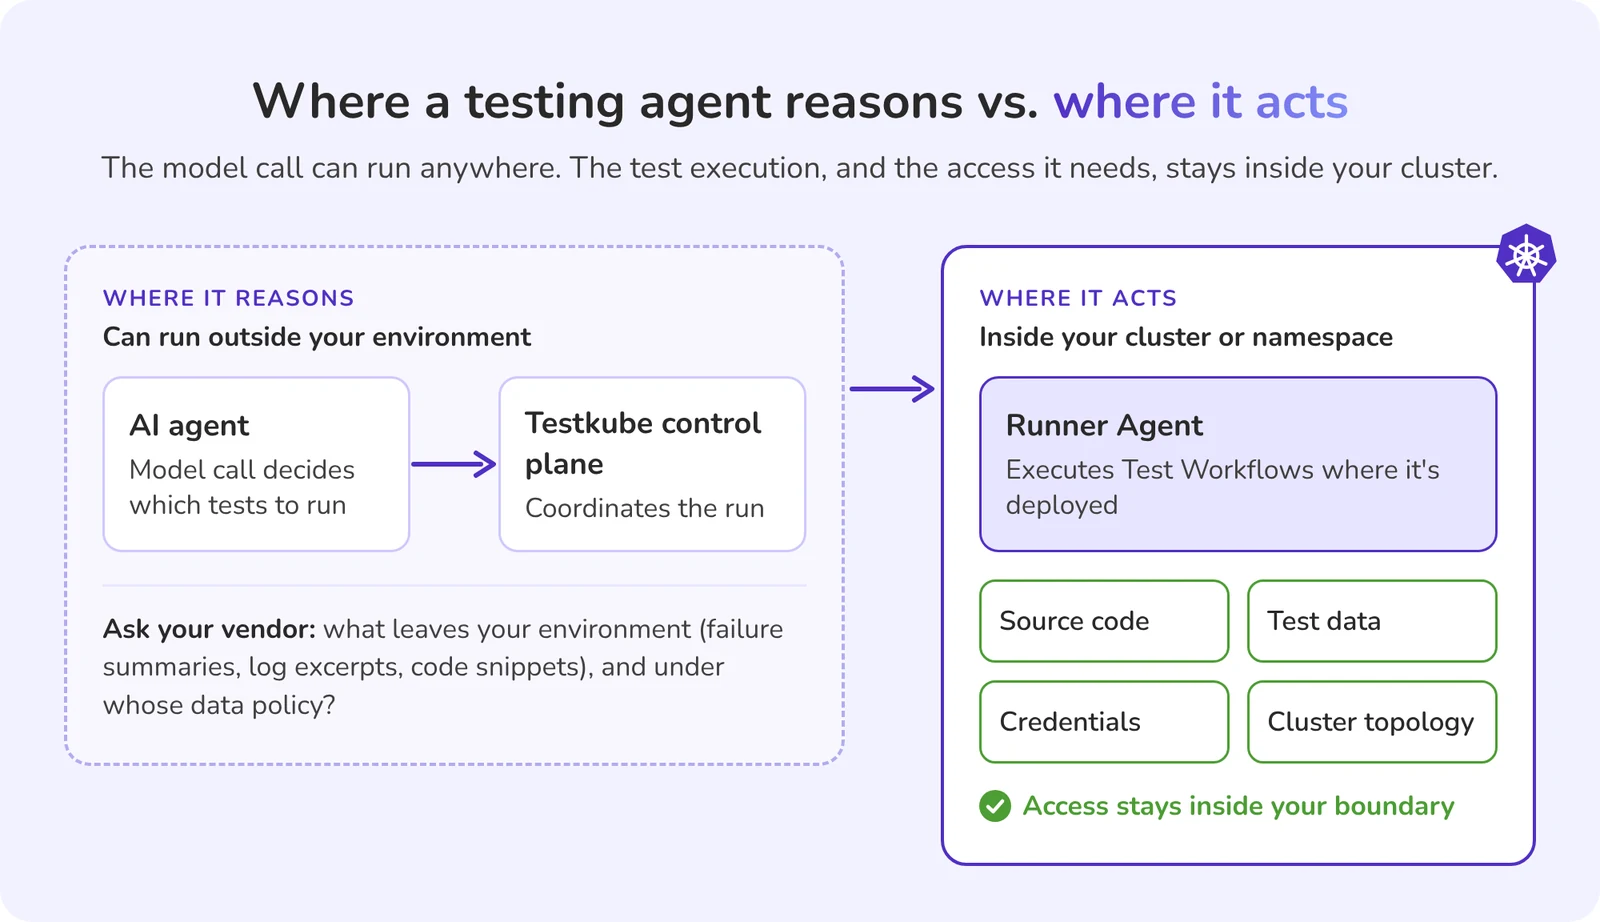
A common mistake is assuming that the interface is the execution layer, but it isn't. An IDE plugin, a terminal command, a chat window in Teams or Slack: none of that tells you where the underlying test execution actually happens. A clean, fast interface running in your browser can be sitting in front of test execution happening somewhere else entirely. The two are often decoupled by design, since that's usually what makes an agent product easy to ship across many customer environments.
What leaves when execution happens outside your environment? Source repositories pulled for context. Test data used during the run. Credentials needed to reach the system under test. The results and logs the run generates, which often carry as much sensitive detail as the source itself. All of it follows directly from where the acting half of the agent runs.
Every vendor has an agent now, so the useful question is where that agent's actions physically execute. That question has a concrete, checkable answer.
Why should testing AI agents execute in your environment?
Testing AI agents should execute inside your environment because that boundary is the one control a team fully owns. If where an agent acts is the real risk surface, gating that action behind a boundary in your own environment is the control that makes everything else possible.
Compliance frameworks matter, but they're not the only solution to this problem. The governance question that's actually top of mind for most engineering leaders is narrower: who can access which agents, what limits apply to how much they can do, what restrictions exist on the underlying models in use, and whether every run is tied to the same agent definition instead of a version someone built locally on their own machine.
Role-based access control (RBAC) often governs who can use tools, but agent governance also needs to define what the agent itself can access. Access control here is about which tools and systems an agent is granted access to, which is a different question than which agents a person is granted access to. Testkube's resource access management is one example: it controls which members and teams can reach each Environment and its Workflows, through Environment roles and Resource Groups enforced in the control plane. A testing agent's credentials and scope deserve the same review as any other privileged non-human identity, which ties back to the agent identity gap: only 21.9% of teams treat an agent as its own identity.
Environment parity is a real bonus, even if it's secondary. An agent running against your actual cluster and actual service topology catches things a sandboxed or externally hosted execution never will, since it's reasoning over what's actually true about your systems rather than an approximation of it.
The same access that makes a testing agent useful is exactly what creates its risk profile. Containing where it's allowed to act, through a governed boundary rather than open reach, is the lever a team actually has. Nobody can meaningfully reduce what a testing agent needs to see. Every team can control the boundary it has to go through to see it.
What should you ask vendors about AI testing agents?
Once you separate reasoning from execution, the buying questions become much clearer, and making the case for why execution location matters becomes easier. Here are four questions worth asking of any AI-powered testing tool, and what separates a real answer from a vendor dodge.
What does the agent need access to?
A specific, scoped answer names the exact systems, repositories, and data categories involved. Something like "read access to this repo, write access to open PRs against this branch, read access to these three telemetry sources" is a real answer. "It needs visibility into your environment" is not. It's a sentence built to sound complete without committing to anything checkable. If a vendor can't enumerate the access list on request, it hasn't actually been scoped.
Where does that access actually execute?
This is the split between where an agent reasons and where it acts, applied directly to a buying decision. Simply ask: does the model call happen off-premises while the tool call, the part that touches your systems, happens inside your infrastructure? Or does everything, reasoning and acting both, leave your environment?
Testkube is useful here as a concrete example of this architectural pattern. Its agent architecture gives teams a documented answer to the execution-location question: the control plane coordinates activity, but Testkube runners execute Test Workflows inside the cluster or namespace where they're deployed.
For instance, if an external AI agent connected through MCP decides that tests should run, its reasoning may happen outside the testing environment. But the actual test execution can still be routed through Testkube runners deployed inside your own cluster or namespace. In that model, Testkube becomes the governed execution boundary for the agent's actions, rather than just another remote tool endpoint.
What leaves your environment, and under whose data policy?
This covers metadata, logs, and anything sent to a third-party model provider for analysis. The honest version of this answer names the specific data categories that leave (failure summaries, log excerpts, code snippets used for context) and states whose data policy governs them once they do. A vendor that answers with "we take security seriously" instead of a specific list hasn't actually answered.
Is access auditable and revocable?
This ties to the agent identity gap: most teams don't treat an agent as its own identity. Can a team see what the agent did, when, and pull its access without opening a support ticket and waiting days?
Testkube's audit logs are a concrete example of what this looks like in practice: every action is tracked by actor, event type, and timestamp, and can be filtered or exported for review. Each call through the Testkube MCP Server is logged as its own event, with the tool called, who called it, the Environment, and whether it succeeded, and the log can be filtered to show only MCP activity.
None of these four questions require the vendor to have a perfect answer. They require the vendor to have an answer at all, one specific enough to be wrong if it turns out to be false.
Execution location is the question that's still open
Every vendor has an agent now, so having one no longer sets a tool apart. The open question is where those agents are allowed to act, and that's the same question you'd ask of any other system granted privileged access to your source code, your data, and your infrastructure.
The access an agent needs isn't going to shrink. What's still fully in a team's control is where that access gets exercised, who can reach it, and whether it can be reviewed and revoked on demand. That's the evaluation that actually matters, and it's a very different one than "does this tool have an agent." For what to test once an agent is in place, see testing AI systems at the model and agent layers.
Frequently Asked Questions
{{banner-get-started}}
About Testkube
Testkube is the open testing platform for AI-driven engineering teams. It runs tests directly in your Kubernetes clusters, works with any CI/CD system, and supports every testing tool your team uses. By removing CI/CD bottlenecks, Testkube helps teams ship faster with confidence.
Get Started with a trial to see Testkube in action.